Inside the APES Workflow Builder
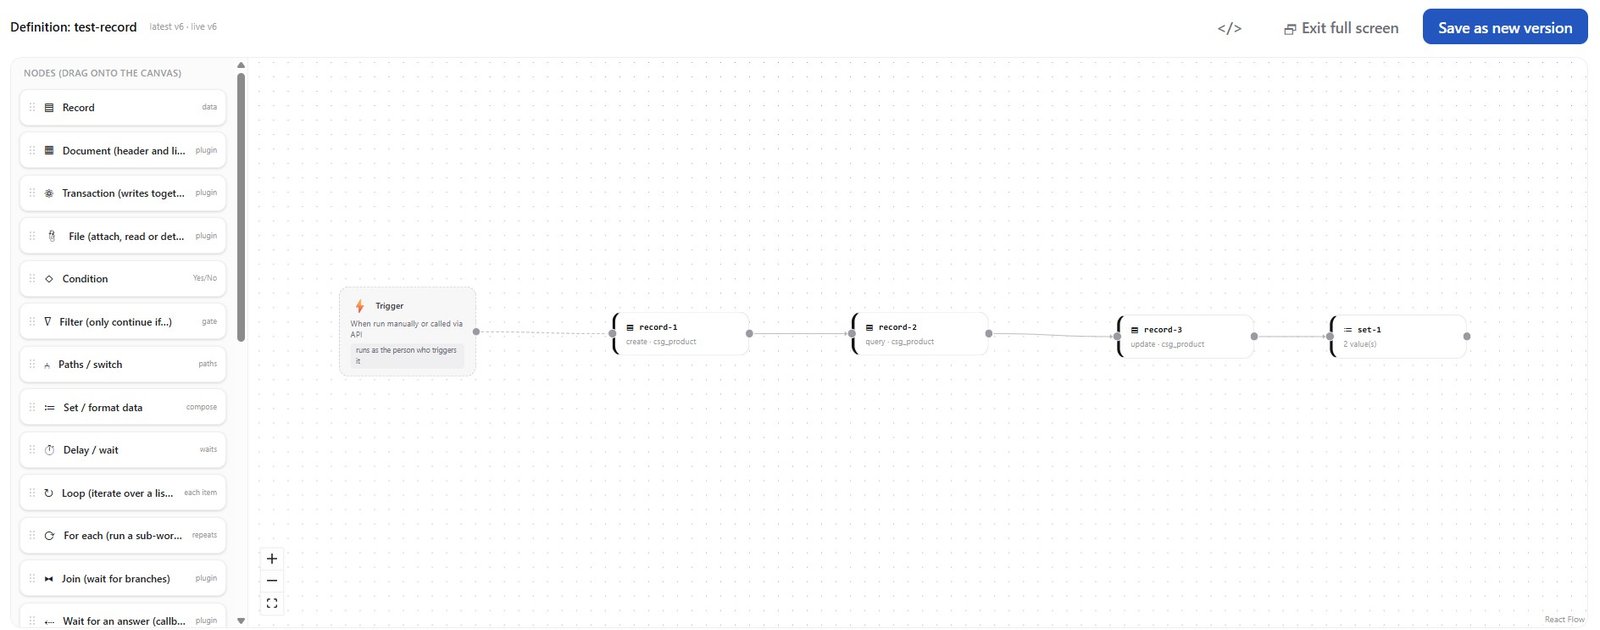
The first post in this series explained that a workflow is built by connecting small, named steps on a canvas. That idea is simple to say and harder to picture until you have actually seen the full set of steps available. APES currently ships with nineteen built in step types, and once you know what each one does, most business processes start to look like a handful of familiar shapes wired together in a different order.
This post walks through all nineteen, grouped by what they are actually for rather than in the order they appear in a menu. The groupings are ours, chosen to make the tour easier to follow, but every description of what a step does is taken directly from how the platform defines it.
The Steps That Touch Your Data
Four steps exist purely to read or write information, and together they cover almost every way a workflow needs to reach into your records.
The record step is the one used most often. It can create a new record, update an existing one, increase or decrease a number on it, delete it, or simply look records up. Most workflows use this step more than any other, because most business logic eventually comes down to changing something in the database.
The document step handles a slightly different shape of data, the kind where one main record has a list of line items underneath it, such as an order with several products on it. It writes the header and every line together as a single act, so you never end up with an order that saved but is missing half its items.
The transaction step, called txn internally, exists for moments where several writes have to succeed or fail as one unit. A stock transfer is a good example. Moving stock from one location to another really means two changes, a decrease in one place and an increase in another, and a transaction step guarantees both happen together or neither happens at all.
The file step is how a workflow reaches into storage. It can attach a file to a record, read a file that is already attached so the workflow can use it, or remove one. It is the step behind anything involving uploaded documents, receipts or attachments.
The Steps That Make Decisions
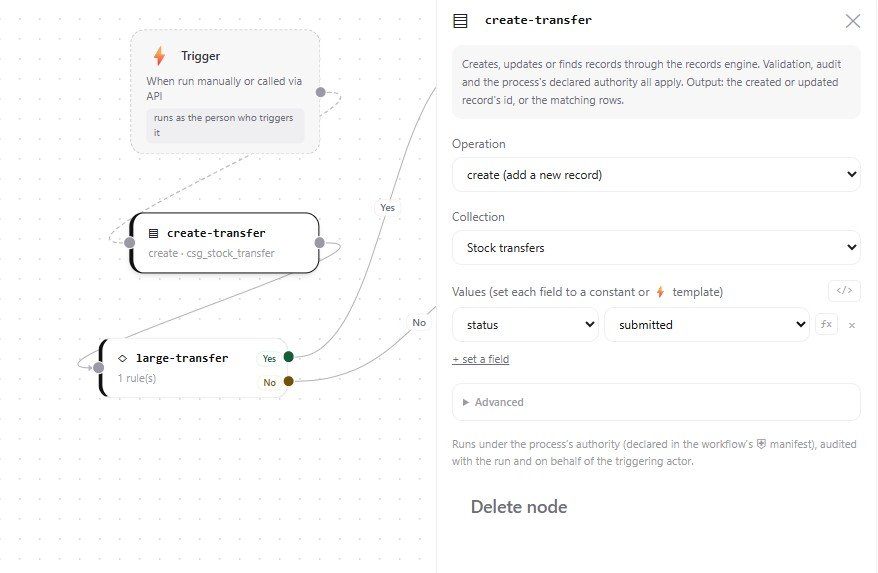
Three steps exist to send a workflow down a different path depending on what is true at that moment.
The condition step asks a yes or no question and branches accordingly. Behind the scenes it can check more than one rule at once, combining them the way a person naturally would, such as checking that an order is both large and unpaid before treating it differently.
The filter step looks similar but behaves differently. Instead of branching into two paths, it simply stops the workflow from continuing at all when its rule is not met. It is the right choice when the rest of the workflow should only run for records that match a certain description, and there is nothing useful to do otherwise.
The switch step is for situations with more than two possible outcomes. Rather than a single yes or no, it looks at one value and routes the workflow down whichever named path matches it, with an optional catch all path for anything that does not match a specific case.
The Steps That Shape and Compute Data
Three steps exist to work something out rather than to read or write a record.
The set step takes information already available in the workflow and reshapes it, renames it, or runs a small calculation on it, such as rounding a number, so that later steps can use a clean value. It never touches your actual data, it only works with information already present in that particular run.
The script step is there for the rare case where nothing else quite fits. It runs a short piece of custom logic in a sandbox that has no access to your data, no access to the network and no access to any secrets, so it is safe to use even for something fairly specific, because it genuinely cannot reach outside the small task it was given.
The function step calls a function that has already been built and registered in your workspace, at a specific version, so that a change to that function later does not unexpectedly change behaviour that already depends on it.
The Steps That Involve People
Two steps exist because most business processes are not fully automatic, and at some point a person needs to be part of the decision.
The human task step is, in a real sense, the reason most workflows exist at all. It hands a decision to a specific person or role, such as approve, reject or amend, and the workflow pauses until they respond. Whatever outcome they choose becomes the path the workflow follows next, which is exactly how the approval example in the first post of this series actually works underneath.
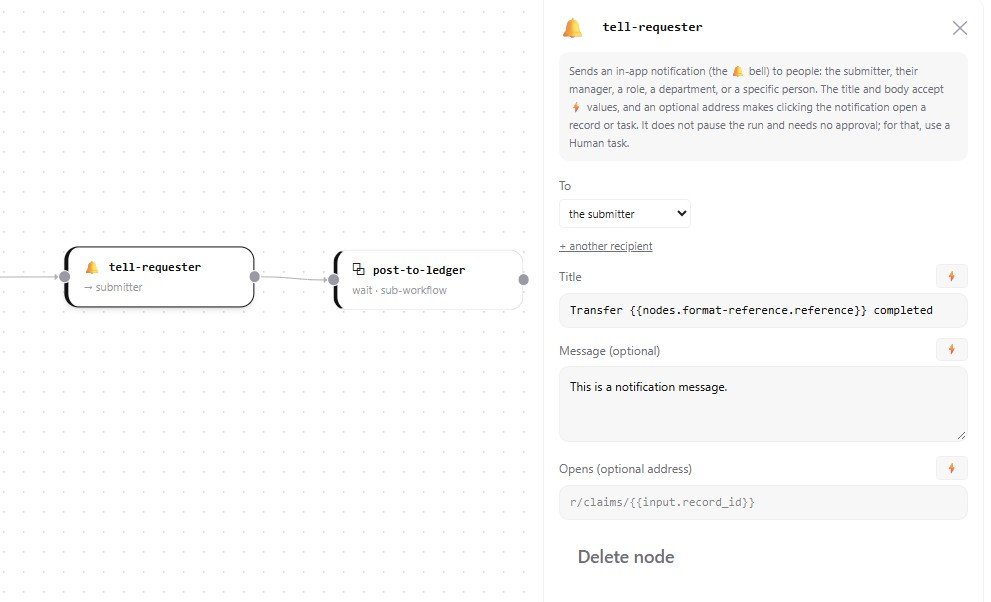
The notify step is simpler. It tells someone something without asking them to decide anything and without waiting for a reply. It is the step behind a message letting someone know their request was approved, or that something needs their attention elsewhere.
The Steps That Wait
Three steps exist to pause a workflow, each for a different reason.
The delay step waits for a set amount of time or until a specific date arrives, and it costs nothing to sit idle for a long time, so it is a reasonable choice even for a wait measured in days.
The callback step is for waiting on an answer from an outside system rather than from a person or the clock. It sends a request out and then waits for that system to call back with a response, which is the shape a real payment confirmation or an external approval usually takes.
The join step matters whenever a workflow has split into more than one path and those paths need to come back together. Without a join step, the first branch to finish carries the workflow forward on its own, even if another branch has not reached the same point yet. A join step makes the workflow wait until the branches you actually care about have all arrived.
The Steps That Repeat
Two steps exist for doing the same thing more than once.
The loop step re runs a small set of steps inside the same workflow once for every item in a list, which suits a short, simple piece of repeated work that is not worth building as its own separate workflow.
The for each step, called foreach internally, instead calls another workflow once for every item in a list, with the actual per item work living inside that other workflow. This is the better choice when the repeated work is substantial enough that it deserves to be built, tested and reused on its own.
The Steps That Reach Outward or Reuse Logic
Two final steps exist to connect a workflow to something outside itself.
The HTTP step is the only way a workflow can reach another system over the internet. Every address it is allowed to contact has to be declared up front, which is exactly the security detail covered in the first post of this series, the one that lets an IT team know precisely what a workflow can and cannot reach without reading every line of it.
The workflow step calls another workflow already built in your workspace, treating it as a smaller piece of a larger process. This is how a complex process stays readable, built from several smaller workflows that each do one clear thing, rather than one enormous canvas trying to do everything at once.
A Scenario: Following One Stock Transfer From Request to Completion
Reading about nineteen separate steps is one thing. Seeing them work together in a single real process is more useful, so it helps to follow one transfer from the moment it is submitted to the moment it is done.
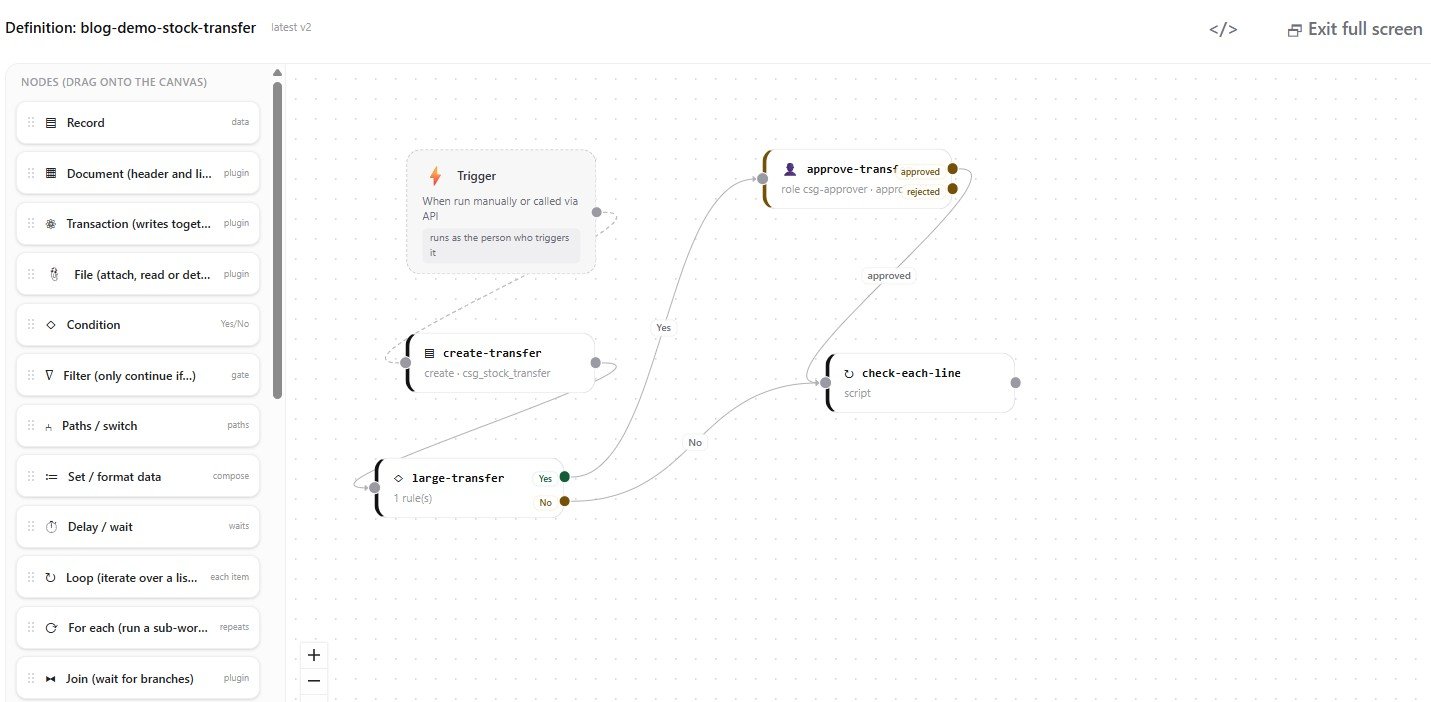
Someone in a warehouse submits a request to move stock from one location to another. A record step creates the transfer as a draft, holding exactly what was submitted. A condition step then checks the value of the transfer. Small transfers move straight ahead. Larger ones are routed to a human task step, which assigns the decision to the right approver and pauses the workflow until they respond. If that approver does not act within a reasonable time, a delay step wakes the workflow back up and escalates the same task to someone else, so nothing sits forgotten in an inbox.
Once approved, a loop step works through each line on the transfer, one product at a time, checking that enough stock actually exists at the source location before anything moves. A switch step decides how the transfer should be handled based on its type, since an internal transfer between two warehouses is treated differently from a transfer going out to a customer. When everything checks out, a transaction step moves the stock, decreasing it at the source and increasing it at the destination as one atomic act, so the business never ends up in a state where stock has left one location without arriving at the other.
With the stock moved, a set step formats a clean reference number for the completed transfer, and a function step calculates its final value using pricing logic the business has already built and registered. An HTTP step then reaches out to notify a connected ERP system that the transfer has happened, calling only the address that workflow was explicitly allowed to contact. If the business wants confirmation that the other system actually received and processed that update before considering the transfer truly finished, a callback step waits for that external system to call back with its answer, rather than assuming the message got through.
Finally, a notify step lets the original requester and the receiving location know the transfer is complete, and a workflow step hands off to a separate, already built workflow that posts the movement to the accounting ledger, keeping that logic reusable rather than repeated inside every process that needs it.
None of this required a single line of code, and every step in it is one of the nineteen already covered. What changes from one business process to the next is not the toolbox, it is the order the pieces are picked up in.
Putting the Pieces Together
None of these nineteen steps are particularly complicated on their own, and that is really the point. A condition step is just a question. A human task step is just a pause for a person to decide something. A notify step is just a message. The value comes from how they combine, and a surprising amount of real business process, an approval chain, a stock transfer, an onboarding checklist, can be built from a handful of these steps connected in the right order.
The next post in this series looks closely at the steps built specifically around people, the human task, notify and callback steps, and walks through exactly how an approval queue behaves from the moment a task lands to the moment it is resolved.